#020 — RAG: The Model Doesn't Have to Remember — It Has to Find
Date: September 25, 2026 | 19:00 London / 21:00 Kyiv
Format: Guest talk · technical deep-dive · ~60–70 minutes
Guest: Oleksandr Blazheiko
YouTube: https://youtube.com/live/ZIyIUK7vGQU
Participants
Oleksandr Blazheiko — Software Development Engineer · Fullstack
Ukraine
LinkedIn · itvibe.party
What we'll cover
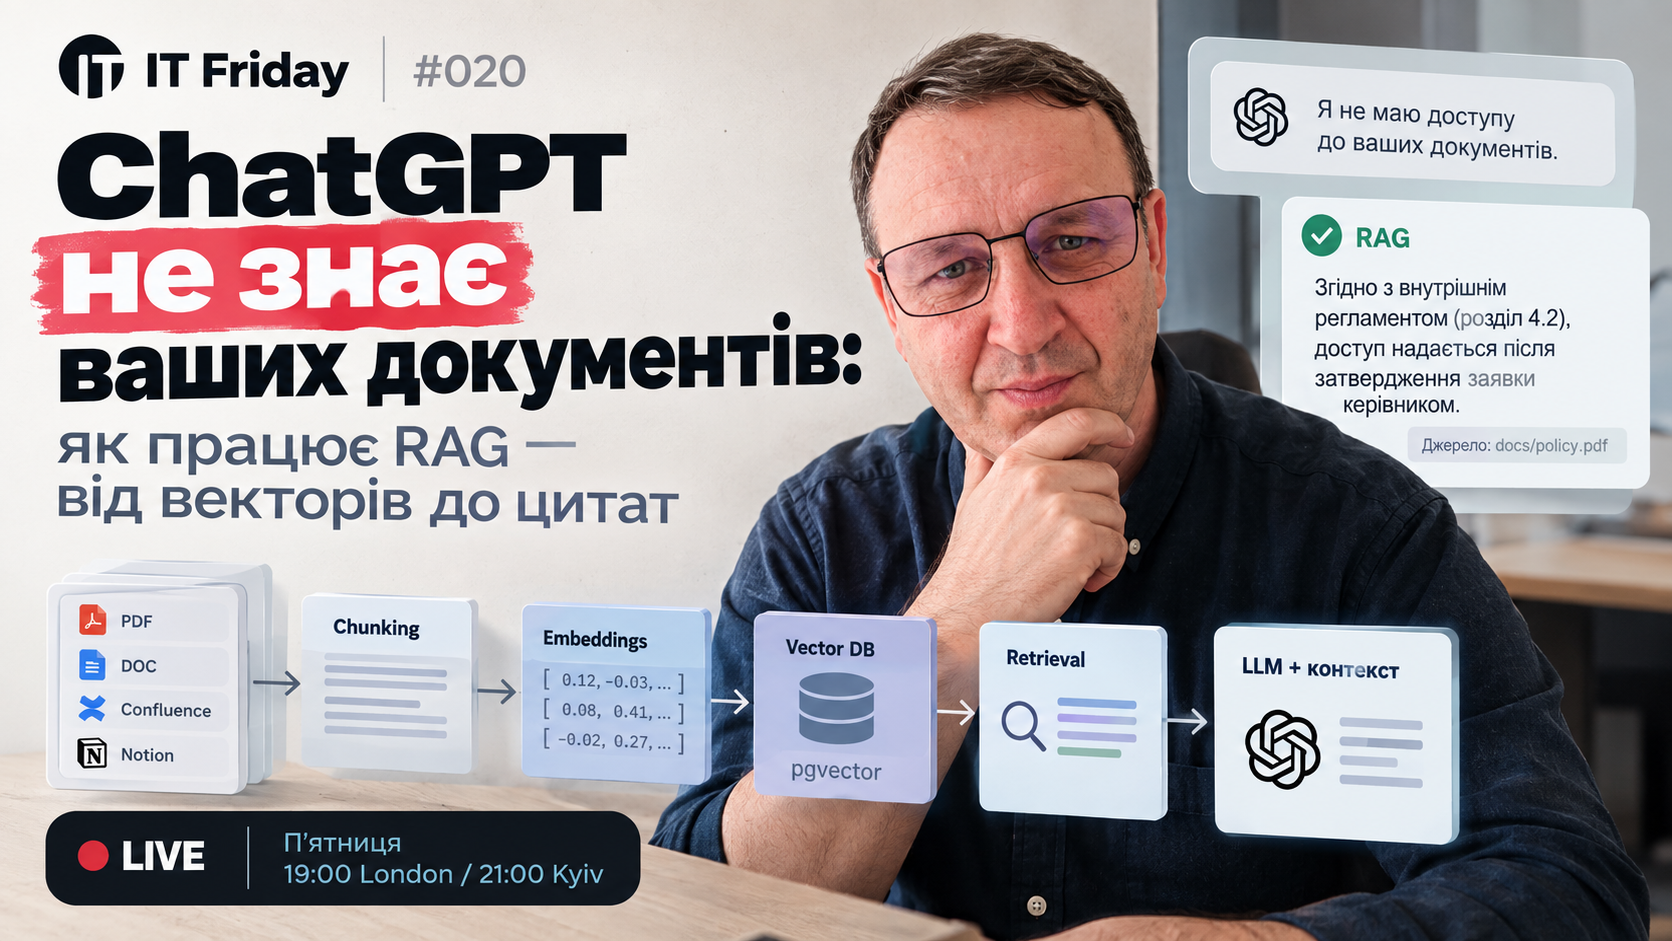
An LLM knows the world up to its training cutoff — and nothing about your documents, policies, or tickets. RAG doesn't change the model: every time, it retrieves the right fragment and puts it in front of the answer. Oleksandr Blazheiko walks through how it works under the hood and why RAG quality is decided by search, not by the model.
Topics
- Why RAG: fine-tuning vs long context vs RAG — what each gives and what it costs
- Architecture: two phases — indexing and querying
- A vector as the meaning of text: embeddings and cosine similarity, explained simply
- Similarity metrics and pgvector: which operator to use and why an index can silently be ignored
- Vector databases: what gets stored, metadata, how HNSW finds neighbours
- Chunking: size, overlap, small-to-big
- Hybrid search (vectors + BM25), reranking, and query rewriting
- Prompts that cite sources and are allowed to say "I don't know"
- Measuring quality: Recall@k, faithfulness, golden datasets
- Common pitfalls — and when you don't need RAG at all
Key takeaways
Added after the stream.
Timecodes
Added after the stream.
Resources
- Slides — RAG: The Model Doesn't Have to Remember — It Has to Find (Oleksandr Blazheiko)
- Lewis et al., 2020 — Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks
- pgvector — vector similarity search for PostgreSQL
- RAGAS — evaluating RAG systems
- itvibe.party — Oleksandr Blazheiko's project
- LinkedIn page
- Telegram community
- Discord server